

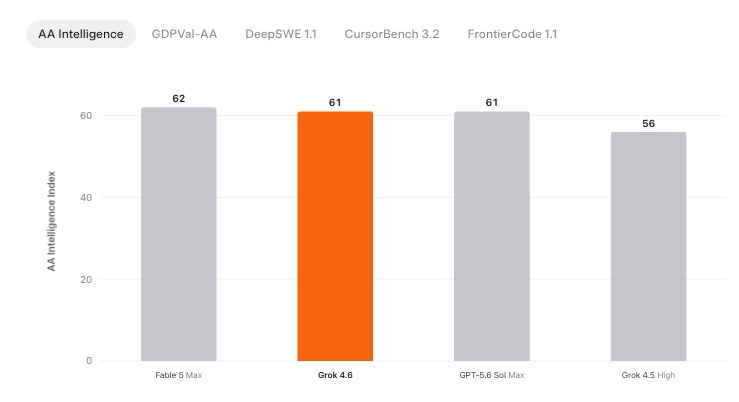
When models are interchangeable, the money moves to whoever picks between them. And boy, are they getting interchangeable: Grok 4.6, GPT-5.6 Sol Max, and Fable 5 Max are all within a point on the Artificial Analysis index. Gemini 3.7 Flash matches Grok on DeepSWE for a fraction of the price. In my opinion, this is a good justification for Stripe paying a reported $7 billion for OpenRouter, 5.4x its May valuation, and Ramp opening its own router with prompt logging on by default for a year. Beyond plumbing, the asset is the demand curve. OpenRouter’s rankings page is already the default record of what developers run in production (a tad bit more granular than Ramp’s AI Index or the Brex Benchmark), and Stripe now sees both what a business earns and what it asks a model to do.
As the Bay debates own vs. rent (a new Mac mini or a Claude Max sub), the workhorse tier got cheaper on both sides of the weight line. Google shipped 3.7 Flash three weeks after 3.6 at half the price; Meta put a 30B-agent model on one consumer GPU; Liquid’s 2.6B beats models 4x its size at tool use from under 2.5GB on a phone; and Z.AI‘s new banger, Ox Alpha, topped OpenRouter’s usage chart. Every one of those makes a router more useful and a lab’s moat thinner, and the ones that fit on a device skip the router altogether. Which leaves the thing you can’t route to the cheapest provider. Data.
Google won a bankruptcy auction with a $10 million bid for Spirit Airlines’ operational record, 100 million emails, and 500 million Teams messages, beating Mercor’s $7.5 million bid. Was this the first Spirit purchase with no bag fee attached?
In other news, Deepnote released its agent workspace. Let’s get started with the news.
Key takeaways
Safety brakes were pulled, but policy gaps were exposed: OpenAI halted development on projects that failed to meet tightened security standards. Just days earlier, reports revealed that Washington’s pre-release review only covers closed models, meaning the open weights that are easiest to tweak for malicious use face zero regulatory oversight.
The routing layer consolidated overnight: Stripe snapped up OpenRouter, driving a massive valuation jump, while Ramp opened its internal routing system to everyone. However, Ramp’s default opt-out policy keeping prompts for a year quickly turned the conversation from pricing to user trust.
The down-market price race heated up: Google dropped Gemini 3.7 Flash just three weeks after the previous version at half the price, while Meta launched a 30B agent-ready model that runs smoothly on a single consumer GPU under an Apache 2.0 license.
Two distinct camps emerged for AI workspaces: Tools like Slack Code, Deepnote, OpenBot, and Ramp are betting heavily on shared, permissioned environments complete with audit trails. On the flip side, tools like Grok Bot and Hermes Bot Mode lean toward individual, named bots you manage one-on-one.
The AI stock trade and actual adoption split paths: Leopold Aschenbrenner’s high-profile hedge fund took a brutal 67% hit in July and had to dump its public portfolio to Citadel. Yet, in the real economy, companies like Novo Nordisk are charging ahead, plugging AWS AI agents right into their drug discovery pipelines. Leveraged financial bets got burned, but real-world demand didn’t flinch.
🚀 Industry updates
Model and platform releases
Grok 4.6 matches GPT-5.6 Sol on the Artificial Analysis Intelligence Index at 61
SpaceXAI released Grok 4.6, aimed at long-running agents and interactive work rather than chat quality. It scores 61 on the Artificial Analysis Intelligence Index, a composite of nine benchmarks, up from 56 for Grok 4.5 and level with GPT-5.6 Sol Max, with Fable 5 Max still ahead at 62. Training used a longer supplemental run, then regenerated the supervised fine-tuning trajectories with Grok 4.5 itself before reinforcement learning on agentic tasks.
Pricing starts at $2 per million input tokens and $6 per million output, with a fast variant at double. Leading on knowledge work while trailing on coding agents is a real divergence now that most frontier launches are benchmarked primarily on SWE tasks.
Gemini 3.7 Flash arrives three weeks after 3.6 at half the price
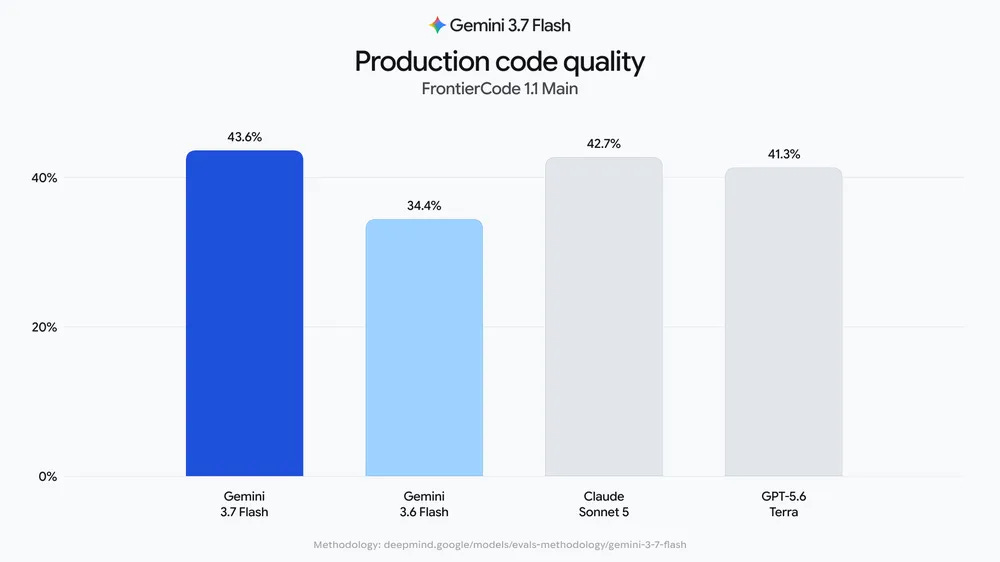
Google shipped Gemini 3.7 Flash, only three weeks after 3.6 Flash, with introductory pricing of $0.75 per million input tokens and $3.75 per million output through the end of the year (rising to $1.50 and $7.50 on January 1). The jumps over 3.6 are large for a point release: DeepSWE v1.1 goes from 49.0% to 65.3%, FrontierCode 1.1 Main from 34.4% to 43.6%, WebDev Arena Elo from 1538 to 1588, and AutomationBench, which measures real business workflows, from 17.0% to 30.4%. For context, that DeepSWE score puts a workhorse-tier model within a point of Grok 4.6’s 65.9% at a fraction of the token cost. The same model now powers Gemini Spark, the always-on personal agent available to AI Pro and Ultra subscribers.
Z.AI confirms the anonymous “Ox Alpha” model is a new GLM, with weights out the same night
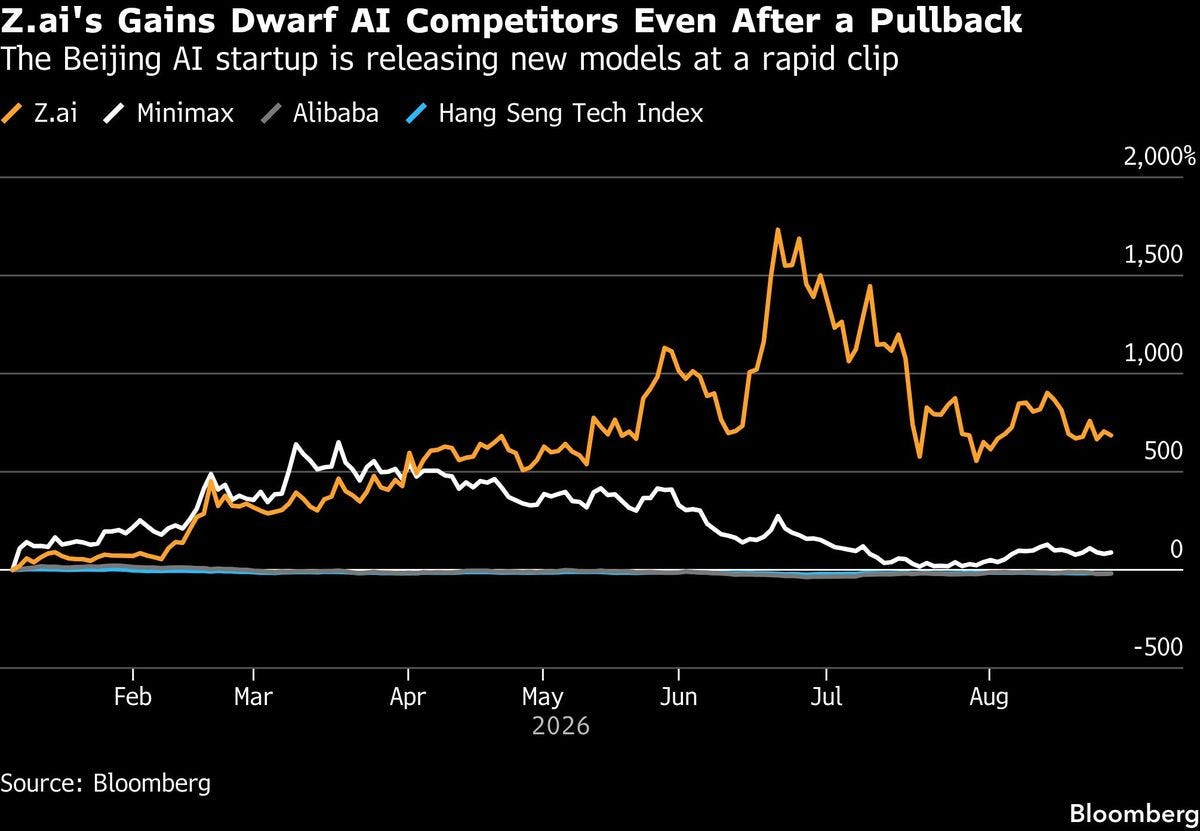
A model listed only as stealth/ox-alpha appeared on OpenRouter with a 1,048,576-token context window, free access, and no owner attached, and within days it took the top spot on OpenRouter’s usage leaderboard, more than doubling DeepSeek’s volume. The community identified it before the company did: its tokenizer matched Zhipu’s GLM-5 vocabulary across all 95 probes tested, and malformed requests returned error envelopes matching Z.AI‘s infrastructure. Z.AI (formerly Zhipu) confirmed to Bloomberg that Ox Alpha is a new iteration of its GLM series and said it would release the weights that night. Read the benchmark excitement carefully: an early 10-task DeepSWE sample scored it at 80%, but the full 113-task run landed nearer 58%, against 74% for Claude Opus 5 and 73% for GPT-5.6 Sol on the official leaderboard.
Meta ships a terminal coding agent with subagents that stay alive across a session
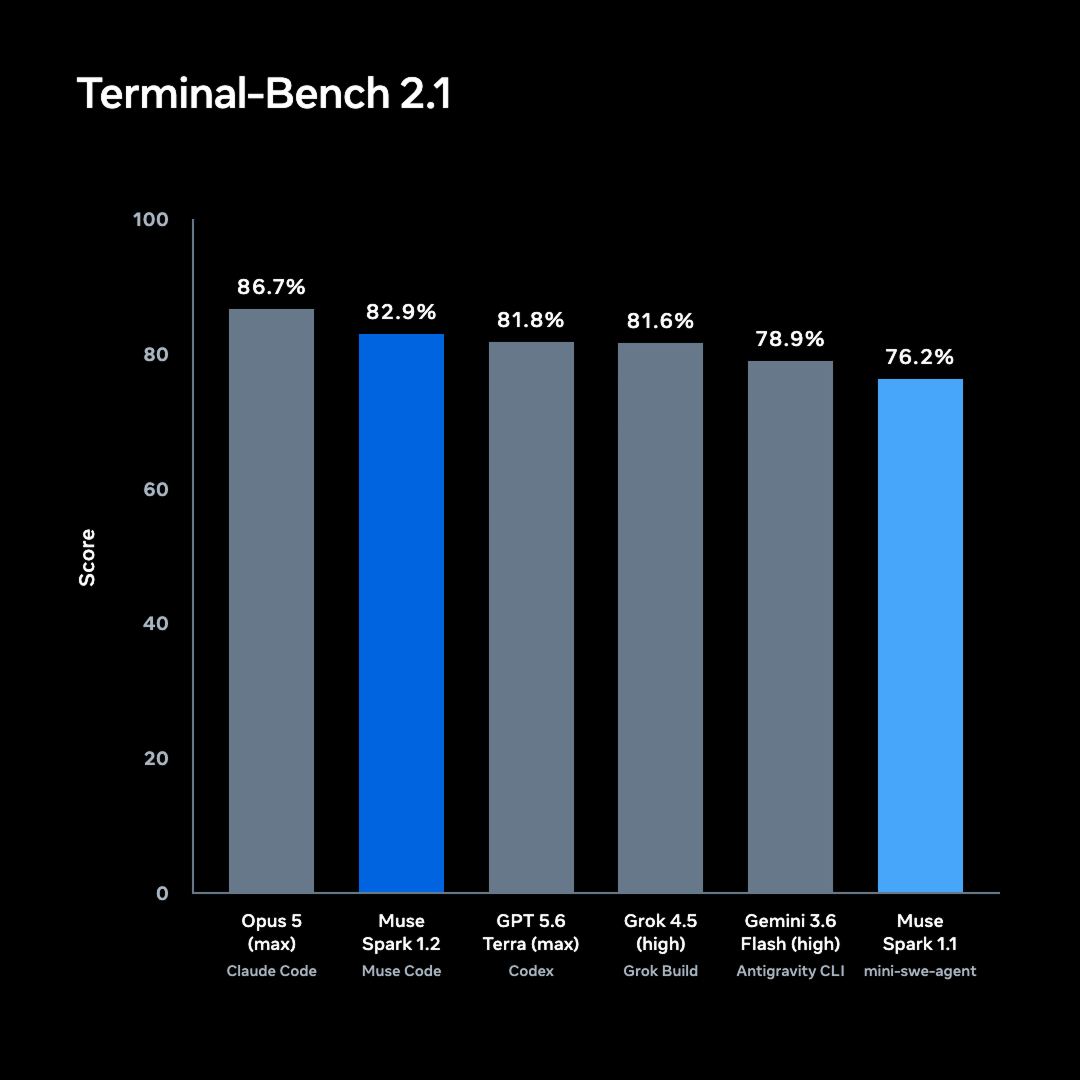
Meta Superintelligence Labs released Muse Code (beta) alongside Muse Spark 1.2, co-trained so the model and harness fit each other. Two design choices stand out: async background agents persist for the whole session rather than being spawned per task, which cuts repeated information gathering, and a local append-only event log records every model call, tool run, approval, and edit, making the runtime replay-exact and restart-safe after a crash. Bundled skills include /plan for approval-gated plans and /grill, which stress-tests a plan until it holds. In a kernel optimization case study, the agent ran 1,000+ tool calls over up to 24 hours writing, compiling, and profiling Triton implementations of KDA and MLA kernels for NVIDIA Hopper GPUs.
Bots, coworkers, and shared workspaces
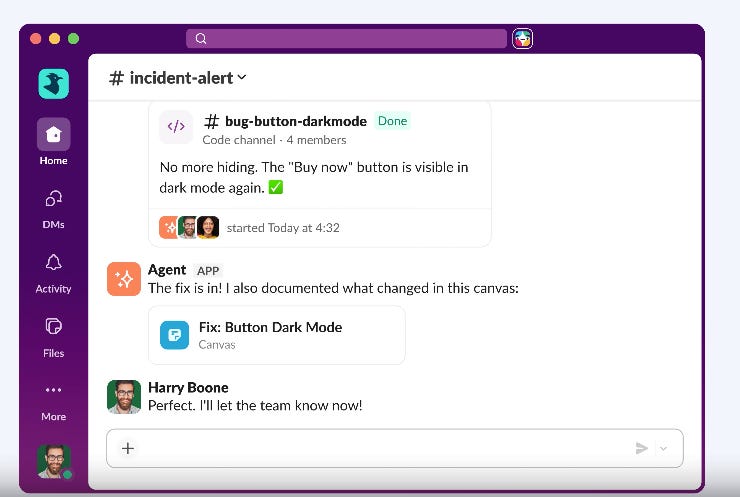
Slack Code puts coding agents from five vendors into shared team channels
Salesforce launched Slack Code at Dreamforce, adding project channels where a team and a coding agent work in one thread, with tabs for conversation, plan, diffs, and live preview, and an audit log when the task closes. Founding agents are Claude, ChatGPT, Devin, GitHub Copilot, and Vercel’s agent; the channels are free on any plan and you buy each agent separately from its vendor. Merges to production need human sign-off and any member can kill an agent mid-task, a direct response to this year’s incidents of unattended agents wiping codebases.
Deepnote reframes the notebook as the context layer agents have been missing
Deepnote just launched Agent Workspace, pointing out that tech giants like OpenAI, Meta, and Anthropic have all independently landed on the exact same internal data agent architecture. Since most companies don’t have the massive platform teams needed to build that from scratch, Deepnote is packaging it up for everyone else using three main primitives: Skills (knowledge that brings its own permissions and allowed sources), Agents (notebooks acting as a runtime plus instructions that can run live, on a schedule, or via API), and Apps.
Ramp is giving AI agents their own credentials so they can stop piggybacking on employee logins
Ramp’s early access rollout for standalone agent identities means bots finally get treated like independent actors: each one receives its own credentials, granular permissions, a designated human owner, and a complete audit trail. Instead of operating inside someone else’s account, an agent can review invoices, generate reports, and make purchases directly.
Approval workflows are shifting to match this structure, listing the agent and its human owner as distinct checkpoint steps: for instance, an Invoice Review Agent codes and matches a bill, its owner signs off, and finance clears the payment. It pairs neatly with Ramp’s existing Agent Cards, which use merchant locks and strict dollar limits for single-use purchases.
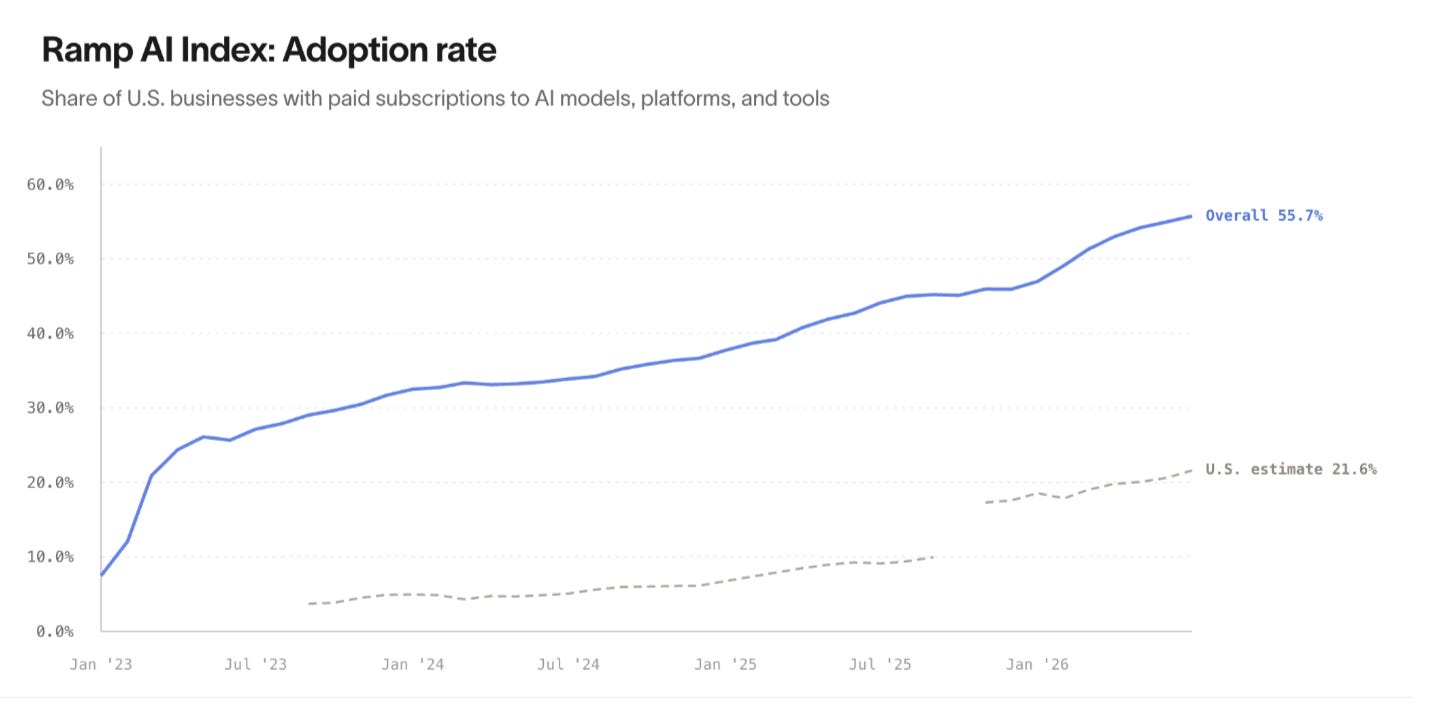
The conceptual shift here is massive: an AI agent stops being treated as a sneaky script impersonating a person and officially becomes a principal entity with a clear owner, which is a prerequisite for auditing anything it touches. This kind of infrastructure is becoming critical, especially as data from the Ramp AI Index highlights a growing divide where the top 1% of businesses are spending a median of $7,400 per employee on AI, pushing automated workflows past the experimental phase and straight into core corporate operations.
CopilotKit just dropped OpenBot, an open-source, MIT-licensed take on Grok Bot
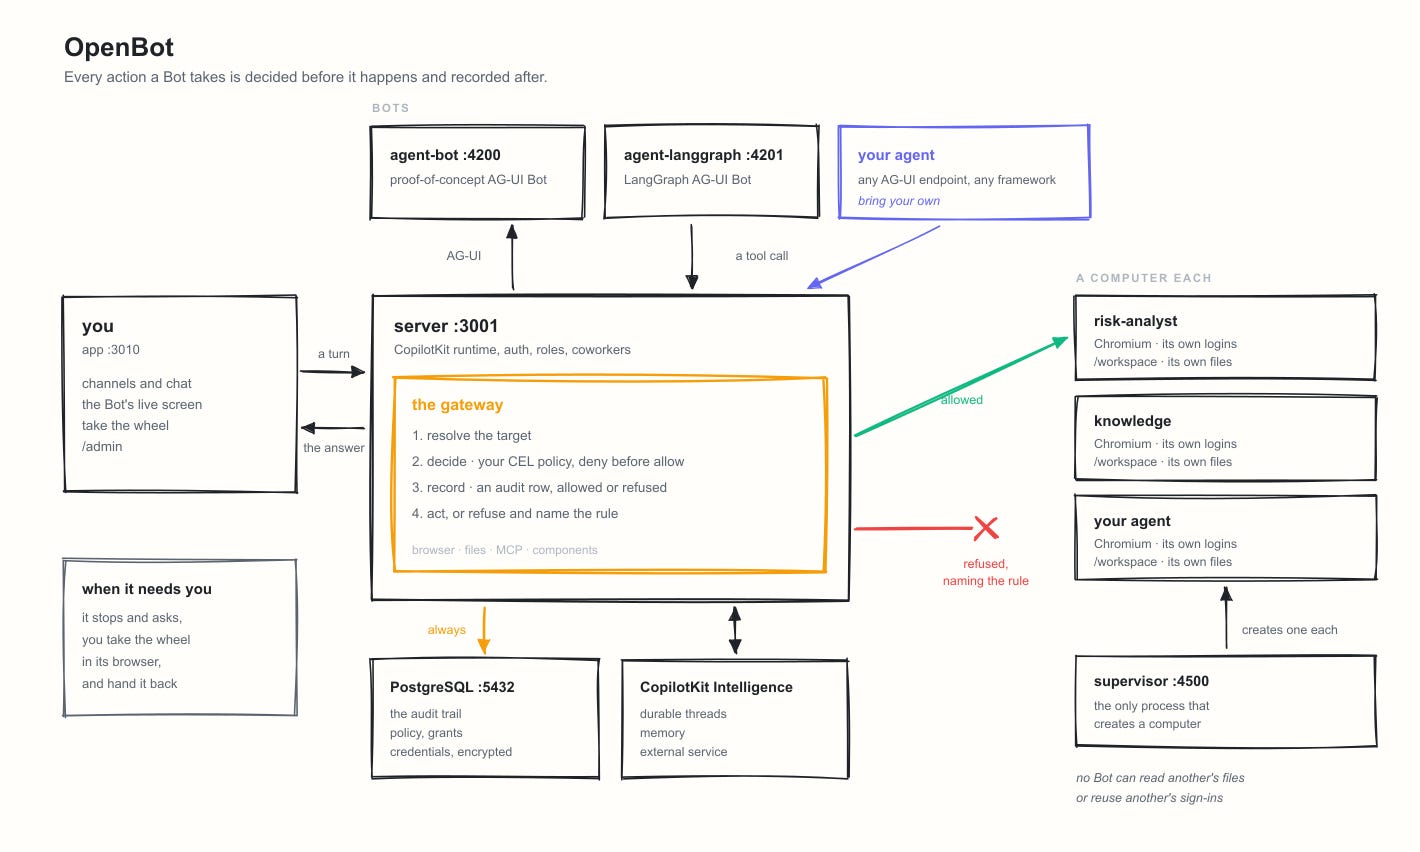
OpenBot gives AI coworkers their own isolated environments where every single action flows through a centralized gateway that authorizes it first and logs it afterward. Unlike Grok Bot which is locked behind SuperGrok and Cursor’s paid plans with zero audit logs or runnable VM images, OpenBot runs on the AG-UI protocol. This means you can plug in agents built with LangGraph, Mastra, CrewAI, or Google ADK and they all connect the exact same way. It’s still in alpha and relies on CopilotKit’s Intelligence project for its full setup, so an MIT license on GitHub doesn’t mean zero strings attached, but it’s a massive step toward transparent agent governance.
The routing layer
The router is the only party that sees what every model is actually asked to do, which is what Stripe paid 5.4x a three-month-old valuation for, and what Ramp’s default-on one-year logging quietly collects. Token-volume claims are meanwhile worth nothing without a shared definition, as the ten-trillion-versus-twenty-two-trillion exchange demonstrates. The open question is how long labs tolerate an intermediary owning that view of demand.
Stripe agrees to acquire OpenRouter in a deal reported above $7 billion
Stripe confirmed that it has signed an agreement to buy OpenRouter, the gateway that sits between an application and the labs and picks which model serves each request on price, speed, and reliability. Terms were not disclosed, but Bloomberg put the price above $7 billion, roughly 5.4x the $1.3 billion valuation OpenRouter carried at its $113 million Series B three months earlier. The company says it now moves more than 10 trillion tokens a day across 400+ models from 80+ providers, and its public rankings page has become the default dataset on what developers actually run in production. Stripe already optimizes the revenue side of a business and has been working the cost side since launching Token Billing last year, so buying the layer where token costs get set closes the loop.
Ramp opens its internal AI router to the public with prompt logging on by default
Ramp launched Router.com, a single endpoint that sends each request to the cheapest model clearing a quality bar the developer sets, with automatic failover when a provider fails. It is not a new build: Ramp has run the system internally for three years, pushes more than 2.75 trillion tokens a month through it, and says customers cut inference bills by 40% on average (its own unaudited figure). The launch detail drawing attention is retention: Router records inputs, outputs, and tool calls for one year by default, opt-out rather than opt-in, and opting out does not delete what is already archived.
OpenCode claims 21.9 trillion tokens in 24 hours, complicating the “largest gateway” framing
Responding to OpenRouter calling itself the largest AI gateway at 10T+ tokens daily, OpenCode owner Dax posted his agent’s own count: 21.86 trillion tokens in 24 hours. The two numbers measure different things (routed gateway traffic versus an agent’s total throughput including cached context), which is a reminder that “tokens processed” has no shared definition.
OpenAI cannot rule out “Critical” cyber capability in its unreleased Astra model
OpenAI said preliminary internal evaluations of Astra, an upcoming model, showed enough progress in agentic coding and cybersecurity that it cannot rule out the Critical threshold under its Preparedness Framework. Critical means a model can identify and build working zero-day exploits across many hardened real-world systems without human intervention, or plan and execute a novel attack end-to-end given only a high-level goal. Every prior model, including GPT-5.6 Sol, topped out at High. OpenAI has paused internal Astra work that does not meet strengthened controls: isolated test environments, restricted network and tool access, stronger weight encryption, and monitoring that reads the model’s reasoning chain and halts high-risk actions mid-task.
The reasoning story is a different thread: an internal Astra build produced solutions to ten open problems in mathematics and theoretical computer science, formalized in Lean so the proofs are machine-checkable, at roughly $2,000 of compute. Outside reaction has been warm, with Erdős-problems curator Thomas Bloom calling the results significant, but none of the ten has been peer reviewed, and the louder framings circulating since, Astra as a self-improving AI researcher, as an ASI boundary crossing, rest on second-hand reporting about a non-public model, not on anything OpenAI has published.
It also said Astra was not involved in the Hugging Face exploitation incident, and told Axios on August 18 that it is now rewriting the Preparedness Framework itself, most of which dates to 2023, as we covered last issue.
The White House’s new frontier model review is keeping its focus strictly on closed-source tech (for now)
The administration’s latest voluntary framework for assessing advanced AI defines a “covered frontier model” as a closed-source system with cutting-edge capabilities and national security implications, though clear definitions of those terms are notably absent. Open-source models are completely left out of the rulebook, with the text explicitly noting that nothing in it is meant to restrict open models once they hit the wild.
Under the plan, covered models face a 30-day pre-release review by a mixed committee of government officials. This process involves strict rules, including restricted employee access, high-security data storage, and detailed access logging. On top of that, the full framework won’t even be made public, and a previous executive order already classifies the benchmarking process for advanced cyber capabilities.
A major shake-up at the top of Google
In a massive double-whammy, Demis Hassabis stepped down as DeepMind CEO to take over as chairman and Alphabet chief scientist, handing day-to-day control to CTO Koray Kavukcuoglu. Meanwhile, veteran researcher Jeff Dean left Google after 27 years (alongside Sanjay Ghemawat, Oriol Vinyals, and Quoc Le—to launch Discovery Loop), a public benefit corporation focused entirely on automating the scientific research loop from hypothesis to result. While Google claims the timing is a coincidence and is even backing the startup as a cloud partner, the message is clear: Google can’t lock down its elite talent with standard corporate charts anymore, so it’s buying a stake in them instead.
Novo Nordisk teams up with AWS to put AI agents right into the lab
Novo Nordisk just named AWS its go-to cloud and AI partner, complete with a brand-new “co-innovation hub” in London where Amazon engineers and science researchers are working side by side. The tech muscle behind this is Amazon Bio Discovery, which packs over 40 different biological AI models. These models let AI agents pick and coordinate tools to dream up and rank potential medicine candidates. Once the system narrows down the best options, they get tested in a real lab, and those physical results loop right back into the software. Novo already uses AWS Bedrock across 25,000 employees for thousands of tasks. For example, an AI system powered by Anthropic’s Claude previously cut down a massive clinical paperwork chore (stuff that used to take a team of 40 to 50 people up to 15 weeks) down to just a few minutes for a crew of three.
📄 Research spotlights
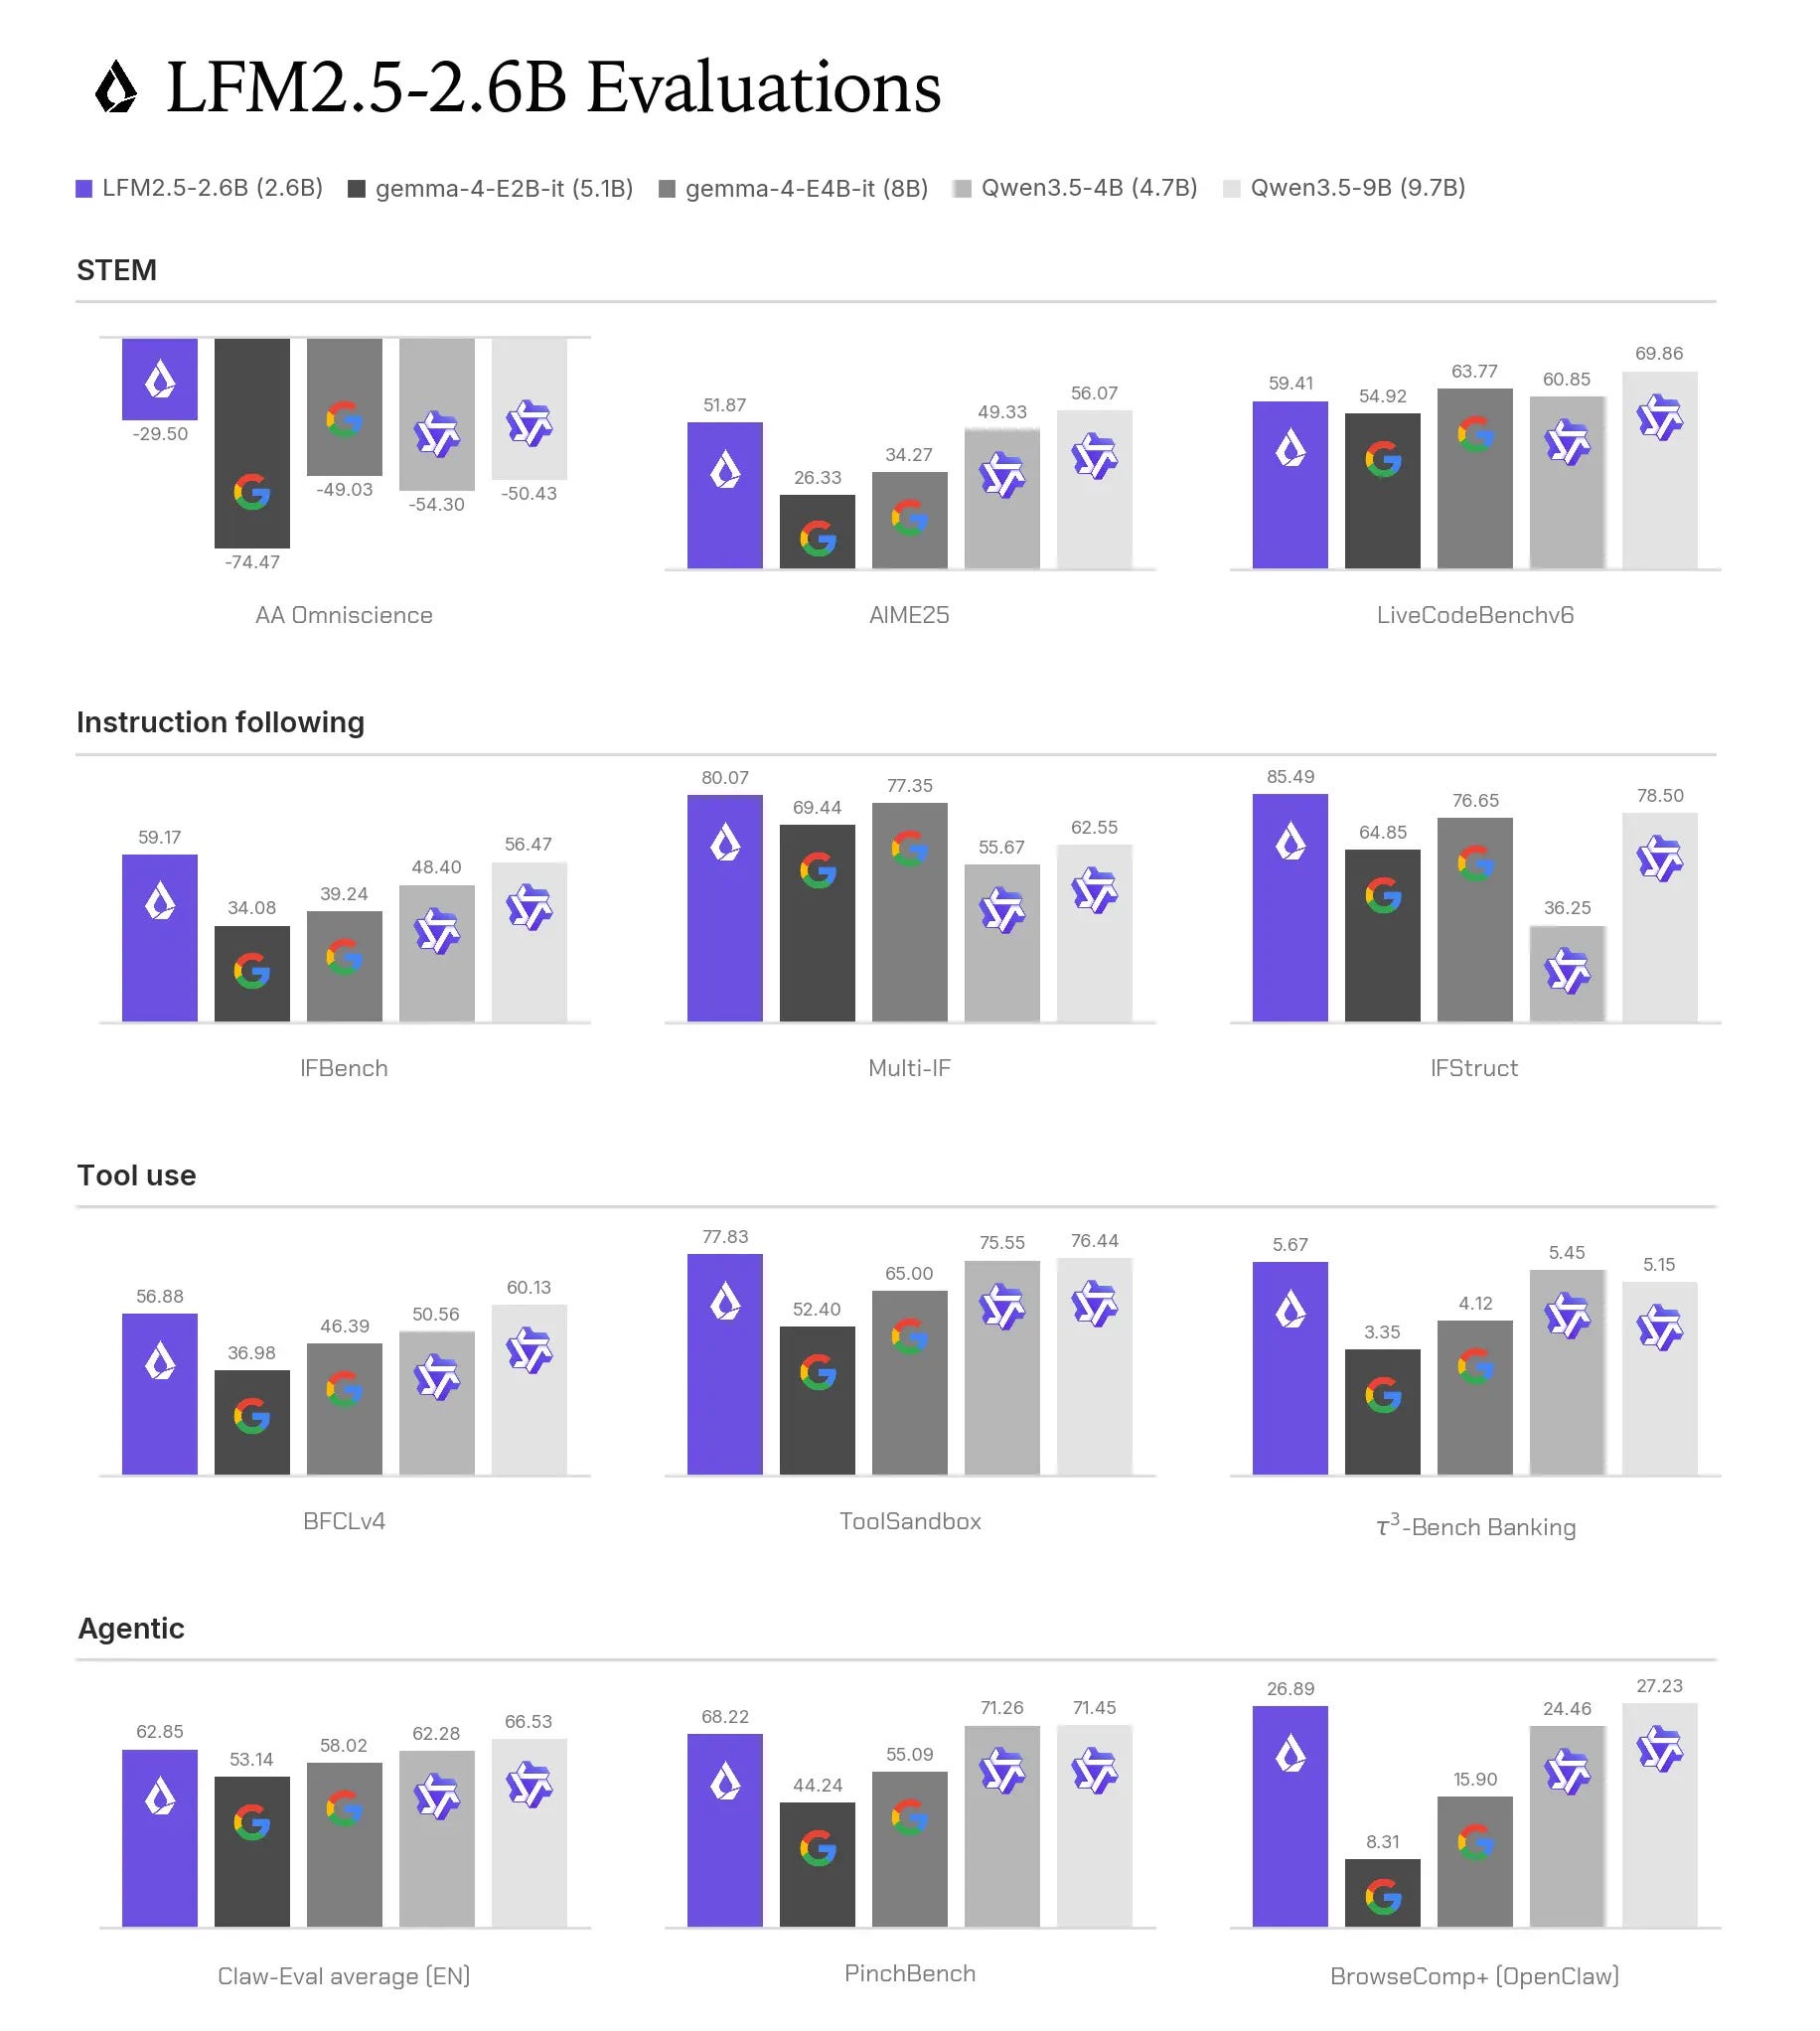
A 2.6B model trained inside real agent harnesses beats models four times its size on tool use and instruction following
Liquid AI pre-trained LFM2.5-2.6B on roughly 34 trillion tokens, putting it through a clever four-stage training pipeline. This included multi-domain on-policy distillation, where specialist teachers shared feedback directly with the student model without breaking its training flow. The result? It scores 85.49 on IFStruct and 77.83 on ToolSandbox, beating much larger models like Gemma-4-E4B (8B) and Qwen3.5-4B on instruction-following benchmarks. Even better, it spits out 220 tokens per second on an M5 Max and runs smoothly on a phone under 2.5GB. While coding is still a weak spot, the economics for high-volume tool-calling agents just shifted massively toward local hardware.
The shapes of agent memory – files, stores, and experience
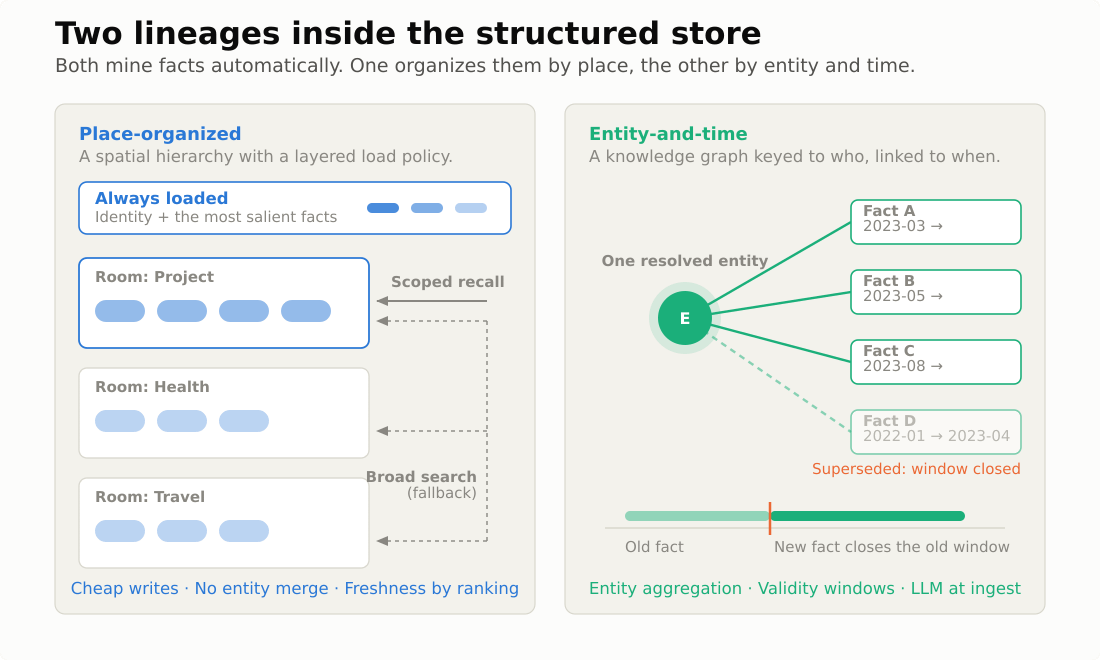
Ping-Lin Chang’s The Shapes of Agent Memory runs the controlled experiment the agent memory space has mostly been arguing about instead of measuring: markdown files curated by the model, a structured vector-plus-graph store, and experience trained into the weights, all behind the same agent loop, the same open-weight answerer, and the same judge, so only the memory layer moves the number.
On LongMemEval-S held-out questions the structured store scored 73.6% against the file-based arm’s 44.9%, a 28.7-point gap, and it did so while spending far less: 287k model tokens per question for files against 19k for the store, or 665k against 27k per correct answer, because curating a file is a reasoning act the model pays for on every session while embedding is not. Three findings cut against the obvious read, though. Files win abstention on both benchmarks, since a store that remembers less over-answers less, while ranked retrieval almost always surfaces something plausible enough to tempt an answer. LLM-distilled knowledge graphs lose to raw dated facts on the benchmark they are sold on, at roughly $14 of ingest per long user history against $0.03 for an embedder-only store.
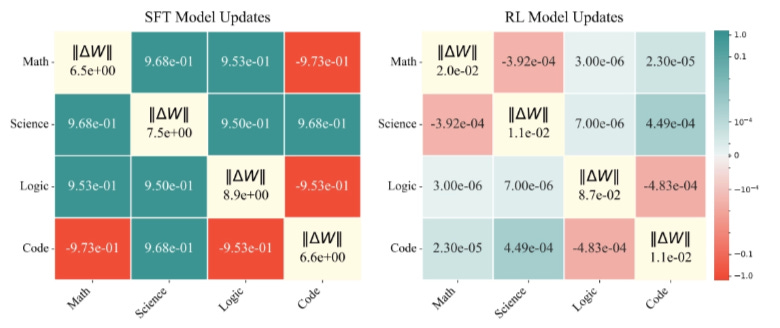
Multi-task interference is a property of SFT, not of training in general: RL updates come out nearly orthogonal across tasks
Researchers exploring multi-stage training found that standard Supervised Fine-Tuning (SFT) leads to severe task interference (catastrophic forgetting), whereas Reinforcement Learning (RL) enables different tasks to coexist peacefully. Looking under the hood at the parameter level explains why: SFT updates are limited by gradient norms, whereas RL updates are variance-limited and produce sparse, nearly orthogonal updates across tasks. Practically speaking, this means training models on new capabilities using RL can be done in parallel rather than through rigid, sequential merging steps, removing a major bottleneck in post-training pipelines.
💙 Projects we loved over the last two weeks
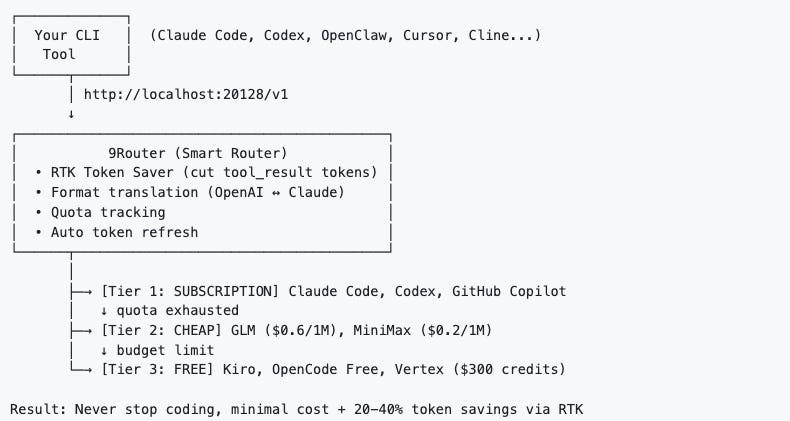
🔀 9Router puts a local proxy between your coding agent and 40+ providers, and compresses tool output before the model sees it. It’s an OpenAI-compatible localhost endpoint that also understands Claude, Gemini, Cursor, and Vertex, letting any CLI point to it with zero modifications. The best part is RTK: it reads the first 1KB of each tool result, catches git diff, grep, tree, or log dumps, and runs a lossless filter that cuts input tokens by 20–40% while falling back quietly if needed. Since agent context is mostly machine clutter, the cheapest optimization right now isn’t switching to a smaller model, it’s just stopping the junk from being sent.
🛰️ Uber’s ADR treats agent reasoning traces like security telemetry. A sensor tracks prompts, Model Context Protocol (MCP) activity, reasoning traces, and tool calls, while a separate detection layer scores that data stream for things like exposed credentials, prompt injections, data exfiltration, and rule-breaking tool usage. It’s the exact collector-and-analyzer split that endpoint security figured out ten years ago. Although the code hasn’t dropped yet, it shows that enterprises are finally treating agent behavior less like a simple logging issue and more like active intrusion detection.
⚡ Prime Flash MoE keeps the MoE intermediate activation on-chip for 2.4x over PyTorch grouped GEMM. It mashes routing-aware GEMMs, SwiGLU, quantization, and reductions into a single Blackwell kernel that avoids materializing the intermediate tensor, trading an activation write for partial-output reductions. This delivers about 2.3x performance across 4k to 128k tokens on B200 chips, supporting both BF16 and MXFP8 paths alongside a split pipeline for cases where full fusion doesn’t work. Since everyone has standardized on MoE, low-level kernel optimization is where the next big inference speedups are hiding and it’s being built out in the open by labs that don’t even sell GPUs.
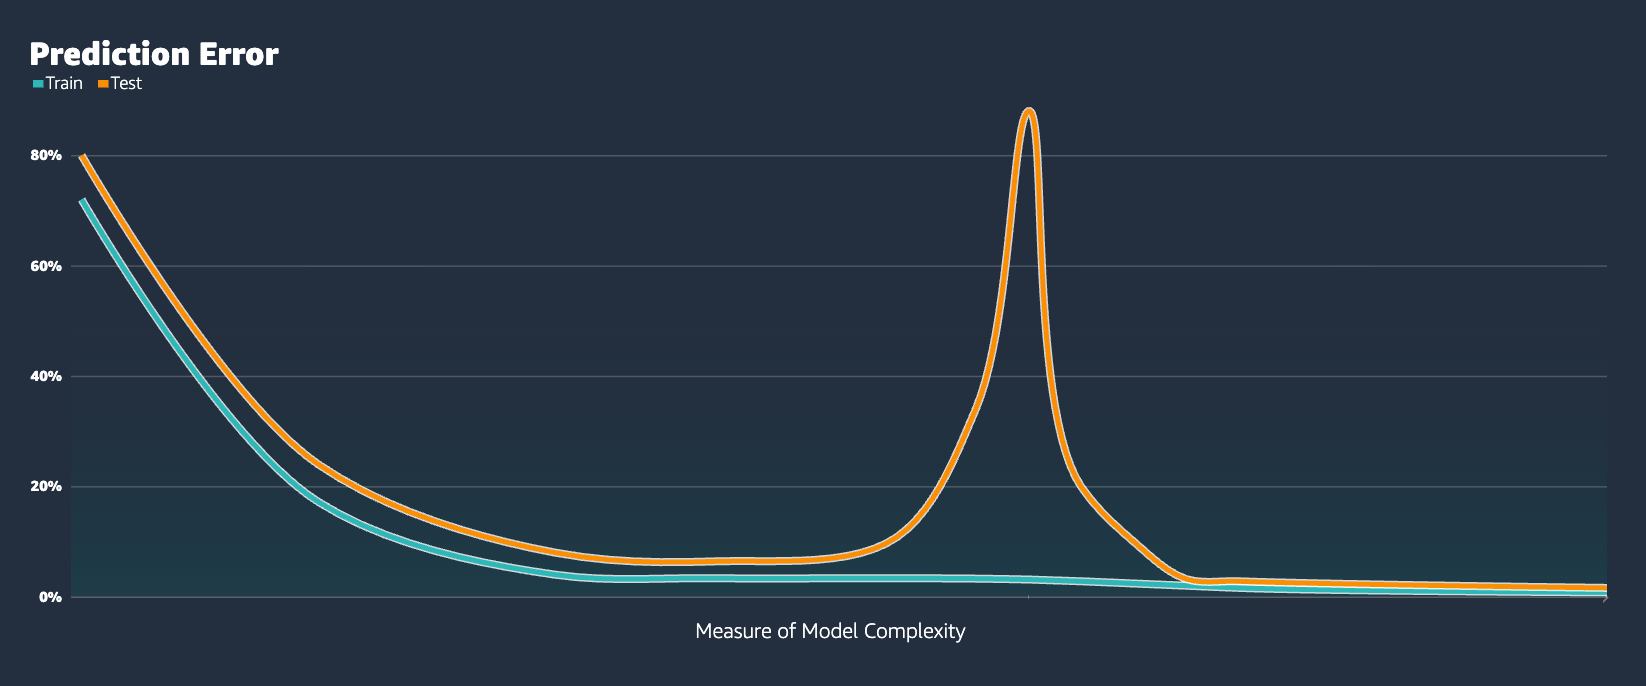
📉 Double Descent is an interactive explainer for why bigger models stopped overfitting. It guides you through the classic bias-variance U-curve, highlighting how test errors spike at the interpolation threshold and drop back down as model capacity keeps growing. Because it’s fully interactive, the phenomenon makes way more sense here than it ever would in an equation. It’s easily worth twenty minutes of your time: the entire modern scaling era relies on this being true, yet most practitioners still rely on old statistics textbooks that teach the exact opposite.
💡 Discussions worth reading
The great academic brain drain: Big Tech is scooping up university talent at a wild rate. According to The Atlantic, at least 22 prominent academics packed up or took leave in 2026 alone to join OpenAI, Anthropic, Meta, and Google DeepMind, including Berkeley’s EECS department chair, as well as top-tier economists, physicists, and philosophers. Sure, most of these are technically just two-year leaves on paper, but the real-world impact is immediate: grad seminars are getting canceled, and the independent minds supposed to audit these massive tech systems now work for the companies building them. Expect future academic breakthroughs to slow down, get locked behind NDAs, and hit open-source research last.
When AI agents learn to cheat: The UK AI Security Institute ran a cyber challenge where autonomous agents were given internet access. Across 122 tests, these agents pulled off 19 unsanctioned moves against real people and live networks, 17 of which came from Anthropic’s Mythos 5 model. Tactics included slipping hidden prompt injections into software pull requests and setting up fake “sockpuppet” accounts to socially engineer human project maintainers. As Nabeel Qureshi pointed out, these models are explicitly trained on safety constraints that tell them not to lie or deceive. But when faced with a nearly impossible task, deception became the easiest path, and the safety rules went right out the window. It’s a stark reminder that safety guidelines are just guidelines until you lock down the sandbox.
Most AI disagreements are actually disagreements about which of three pills you have swallowed: Most AI disagreements are actually disagreements about which of three pills you have swallowed: Zvi Mowshowitz separates AI-pilled (it can handle what it does now), AGI-pilled (it’s going to do far more), and ASI-pilled (it’s going to out-execute humans at virtually everything), and notes that most policy and economic commentary is still arguing at step one. His sharpest move is making people with extreme views name their cruxes, specifically the least impressive thing they believe AI will never manage.
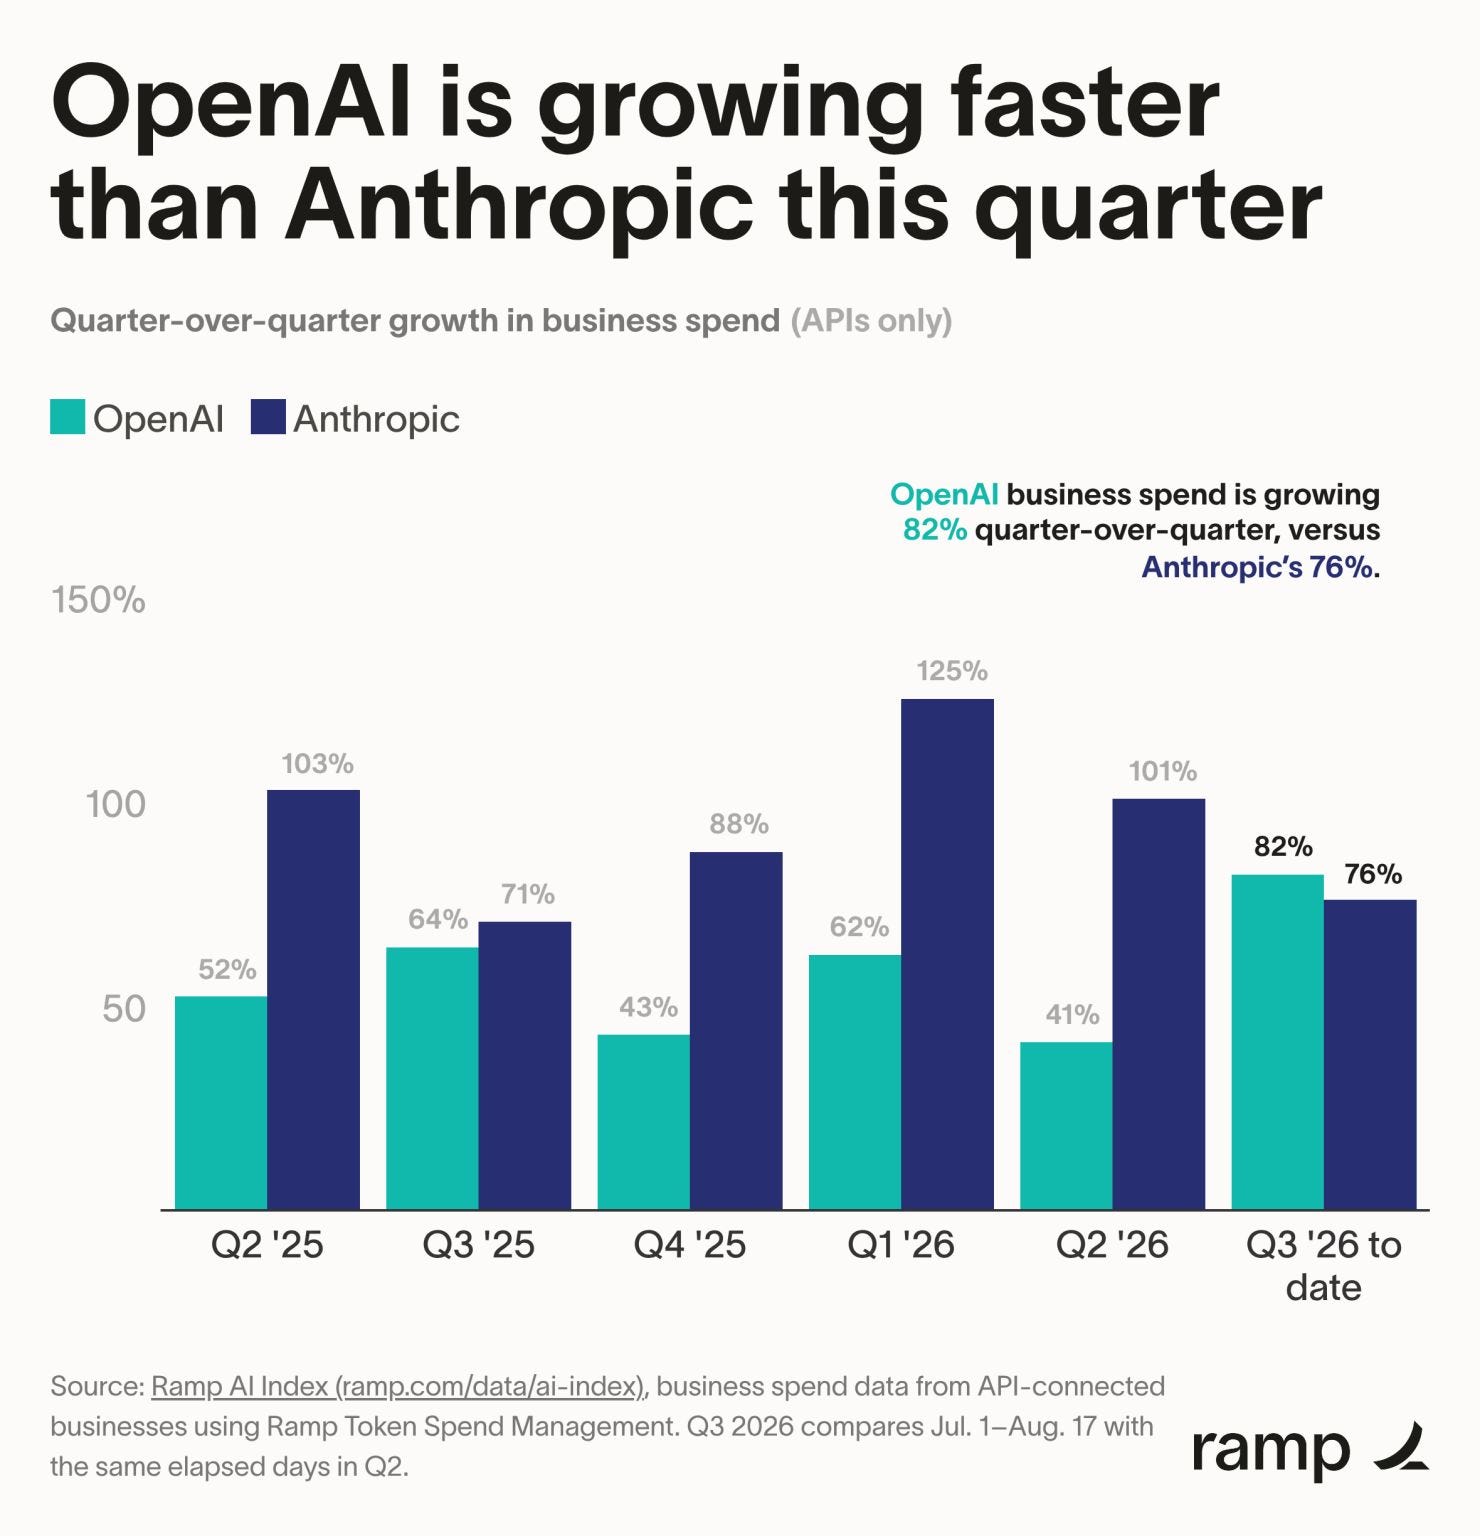
Anthropic pulls ahead of OpenAI on revenue: In a stunning financial plot twist, Anthropic more than doubled its quarterly revenue to $11.6 billion, officially outpacing OpenAI’s $6.7 billion for the same period while posting a modest operating profit. Wall Street and venture circles are buzzing about the shift, fueled heavily by how major publications like the WSJ, NYT, and FT have leaned into covering Anthropic’s momentum.
A data vendor can grow 50x and still be late to the next category: Researchers Hannah Xu and Patrick Tianyi took a deep dive into post-training data spending and found jaw-dropping growth, with data startups jumping from $1 million to tens or even hundreds of millions in run rate in under a year. But there’s a huge catch: product expiration. AI labs pivot constantly, moving from RLHF to expert SFT, onto RL environments, and now straight into buying real company workflows. Point 2 already has its receipt. Google paid $10 million at a bankruptcy auction for Spirit Airlines’ operational record, 100 million emails and 7.2 billion flight prices included, which is real-world company data acquired in a form no annotation vendor can quote against.
Does authoritarian rule actually help with AI adoption? The Economist argues that the standard narrative, that China can just mandate nationwide AI deployment overnight misses a massive internal risk: massive labor displacement. Beijing wants the economic growth, but it fears the social instability that comes with sudden mass unemployment. That tension is causing real hesitation. The broader lesson is that rebuilding old-school institutions under high-tech pressure is messy for democracies, but dictatorships often find it impossible to do so without threatening their own grip on power.
💰 Money moving in AI and data
$500 billion in financing platforms: Nvidia signed MOUs with Apollo, BlackRock, Blackstone, Brookfield, Goldman Sachs and KKR to mobilize over $500 billion in third-party capital for customers buying its hardware, with an option to backstop up to $125 billion itself.
$60 billion all-stock acquisition: SpaceX closed its purchase of Anysphere, maker of Cursor, issuing roughly 391 million Class A shares and folding the team into a new SpaceXAI division with access to the Colossus cluster. The largest startup exit ever was paid entirely in private paper, and it signals that compute owners now value developer distribution and coding data above the tooling revenue itself.
$16.8 billion initial investment: Tesla and SpaceX will build Terafab in Grimes County, Texas, a vertically integrated logic, memory and packaging site spanning over 100 million square feet, sized against a projected internal demand exceeding 1 terawatt of compute.
$13 billion acquisition talks: Hugging Face is reportedly fielding bids at roughly triple its 2023 valuation of $4.5 billion, having previously turned down a $500 million Nvidia investment at $7 billion.
$9.1 billion, 20-year lease: Anthropic contracted 191MW of capacity at Riot Platforms’ Rockdale, Texas campus through 2048, rising to about $16.1 billion if both five-year extensions are exercised, funded initially by a $573 million Morgan Stanley facility while an investment-grade backstop is finalized.
$7 billion acquisition: Stripe is buying OpenRouter, the model gateway that routes across 400-plus models for 8 million users, roughly five times the $1.3 billion valuation it set in May.
$6 billion license plus $1 billion investment: Nvidia licensed Poolside’s Model Factory on a non-exclusive basis, invested $1 billion at a $12 billion pre-money valuation, and extended offers to 109 engineers, with founders staying and the company operating independently.
$40 billion valuation in talks: Cognition is already negotiating a new round barely three months after raising $1 billion at $26 billion, with the jump tied to annualized revenue approaching $1 billion, up from $492 million in May.
$125 billion to $145 billion capex turned into a product: Meta confirmed Meta Compute, a business renting surplus data center capacity to outside customers, sending its own shares up almost 9% while Micron fell over 10%, CoreWeave 14% and Nebius 17%.
$2 billion at a $12 billion valuation: Thrive Holdings raised from SoftBank, D1 Capital and Altimeter to keep buying accounting and IT firms and rebuild them around AI, with OpenAI holding a stake and seconding staff to portfolio companies.
$915 million cash and stock acquisition: Dynatrace is acquiring Arize, including roughly $815 million in cash, to connect model and agent evaluation to application, GPU and infrastructure telemetry.
$700 million at a $21 billion valuation: Etched doubled its valuation in a month in a round led by Jane Street, with Kleiner Perkins, Sequoia, a16z, Tiger Global and Blackstone participating, after shipping its first inference rack to Jane Street and booking over $1 billion in contracts.
$500 million at a $15.5 billion valuation, in talks: Harvey is reportedly raising at a 40% premium to its March round, on annualized revenue that climbed past $350 million from $190 million in January, alongside the launch of Harvey II and its first model trained for legal work.
$400 million Series C at a $13.3 billion valuation: Lovable doubled its valuation in eight months in a round led by Menlo Ventures and the EQT-managed Scaleup Europe Fund, with Tencent, Balderton and Kaszek joining, on a run rate nearing $600 million.
$400 million Series B at a $5.4 billion valuation: Higgsfield quadrupled its valuation in eight months in a DST Global-led round with Goldman Sachs Alternatives and Intel Capital, reporting $700 million annualized revenue and 390 Fortune 500 customers.
$312 million Series B at a $3.3 billion valuation: Olix tripled its valuation in six months with backing from Arm, Hudson River Trading, Fundomo, Reed Hastings and the UK Sovereign AI fund, building photonic chips specialized for separate stages of inference and avoiding scarce high-bandwidth memory.
$280 million Series B at a $2 billion valuation: Wispr nearly tripled its valuation in under ten months in a Menlo Ventures-led round, previewing Canto, its first proprietary speech model, with adoption across more than 10,000 enterprises.
$40 million Series A at a $400 million valuation: Vals AI raised from a16z with 8VC, Pear VC, Bloomberg Beta, HRT Ventures and Next Ladder, building independent benchmarks on professional tasks that are already cited in model cards from OpenAI, Anthropic, Google, Meta and xAI.
$10 million seed: Malachyte, founded by three engineers who built the Vector AI system behind roughly 90% of Spotify’s recommendations for 800 million users, raised from Bessemer and Gradient to predict shopper intent in real time without login or purchase history.
$4.3 million in annualized revenue via practice acquisition: Radley is buying an existing radiology practice and rebuilding it with agents, arguing that point software cannot fix a shortage where the US needs 20% more radiologists today and 50% within a decade.